A general framework for world model learning
Predictive self-supervised learning (SSL) learns useful representations by predicting in latent space, but why? We prove two fundamental principles of predictive SSL:
- Predictive SSL can recover the true latent variables of the data, even if these variables have stochastic, nonlinear dynamics.
- This recovery works even if the data contains strong, unpredictable nuisance
The framework that allows for these proofs, which we term InfoLDM, is a generalization of existing SSL approaches.

Like joint-embedding predictive architectures (JEPAs), InfoLDM predicts encoded observations without reconstructing the input. In fact, by choosing a specific latent predictive model and entropy estimator we can re-derive popular JEPA approaches:
Gaussian model + logdet entropy → VICReg-style
von Mises-Fisher model + KDE entropy → SimCLR-style
Before discussing the formal framework and proofs in more detail, let's get an intuitive understanding of the results.
Identifying nonlinear dynamics under nuisance
We show that InfoLDM allows to find excellent representations and a predictive latent model for nonlinear, action dependent systems—even if the observations are corrupted by high dimensional nuisance. As an example we use the MuJoCo hopper, with the goal to recover physical hopper states (joint angles, positions, ...) from generated videos.
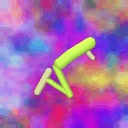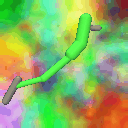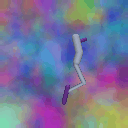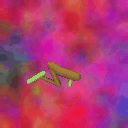
InfoLDM receives the corrupted videos as input and learns a latent model. As comparison we also train generative models that reconstruct the input (additionally to latent prediction). Only the non-generative models find meaningful representations.

We can quantify this with linear readout probes.

Because generative models try to predict or encode every detail in the images, which is too challenging, they consistently fail. InfoLDM directly learns the latents dynamics of the nonlinear system and recovers the underlying variables.
We can also use the learned dynamics to simulate the system: we provide observations for 5 timesteps and query the latent model to generate future trajectories of the underlying physical variables.

Because InfoLDM is based on a probabilistic latent model it is straightforward to get calibrated uncertainty estimates, for example by sampling from it. This uncertainty combines effects of stochastic environment dynamics, observation nuisance, and a potentially imperfect model.
Distinguishing nuisance from signal stochasticity
Recovery under nuisance poses a conundrum: What is considered nuisance and what is only stochasticity in an actually relevant signal, and can the model distinguish those? Our formal results make this precise: Complete unpredictablity → nuisance; predictable signal with added, structured noise → recovered by the algorithm.
To show this we construct pairs of images in which selected factors are causally related, with stochastic variation between the two images. The remaining factors vary independently and act as nuisance.
In the object-signal setting shown below, object position, rotation, and hue are coupled across image pairs. Lighting and background are unrelated. InfoLDM recovers the object (signal) variables such that they can be linearly read out from the representation, while background (nuisance) variables are ignored.

The Signal is defined by the relationship between observations. In a second setting, we couple the environment factors instead of object factors, and InfoLDM recovers the former but not the latter.
InfoLDM: what is recovered, and how
How does InfoLDM allow us to prove this recovery under nuisance? Here is a short overview of the formal framework:

In summary, $c$, $s$ and $n$ denote true latent context, signal, and nuisance variables; $z = f(x)$ is the encoded observation, and $z_c = f_c(x_c)$ is the encoded context. In the simulations above the context is the history and actions (hopper), or the related image, but it can be any relevant encoded conditioning variable. The encoders induce a joint distribution $q_f(z,z_c)$, while a learned latent model $p_\theta(z|z_c)$ describes that distribution. InfoLDM maximizes:
Provable identification of the signal variable
We show that maximizing the InfoLDM goal function allows to recover the signal variable. Under the paper’s assumptions and with a Gaussian predictor, the true signal can be recovered from the learned representation by an affine map:
More generally, we prove this result for exponential family predictive models, where the recovery guarantee is on the sufficient statistics of the distribution.
Assumptions behind the guarantee
- Private nuisance: $n \perp\!\!\!\perp c \mid s$ — nuisance adds no context information given the signal.
- Exponential-family prediction: $p(s\mid c)$ and $p_\theta(z\mid z_c)$ are exponential-family conditionals with sufficient statistics $\tau_\star(s)$ and $\tau_z(z)$.
- Ideal optimum: $D_{\mathrm{KL}}(q_f\|p_\theta)=0$ and $I_{q_f}[z;z_c]=I[s;c]<\infty$ — exact matching and full predictive information.
- Context variation: $\operatorname{span}\{\alpha(c)-\alpha(c_0)\}=\mathbb{R}^{r_s}$ — natural parameters vary in every signal-statistic direction.
- Nondegenerate statistics: $\tau_\star(s)\mid c$ lies in no proper affine hyperplane — no redundant statistic dimensions.
At the optimum of InfoLDM:
The proof shows that the LDM and MI terms serve two complimentary functions:
MI: what is retained
Maximizing predictive mutual information preserves the information shared with the context. At saturation, all prediction-relevant signal information is retained.
This alone does not identify the representation’s coordinates: invertible nonlinear transformations preserve mutual information.
LDM: how it is represented
Latent distribution matching constrains the encoded distribution to follow the learned model. These constraints determine how the retained information is represented.
We show: For exponential-family predictive distributions, InfoLDM identifies the true signal’s sufficient statistics through an affine readout of the learned statistics.
For the full proof and more details, read the paper posted on the arxiv.
BibTeX
@misc{mikulasch2026predictive,
  title={Predictive Self-Supervised Learning Provably Identifies
         Stochastic Signals under Nuisance},
  author={Fabian A. Mikulasch and Friedemann Zenke},
  year={2026},
  eprint={2609.37789},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2609.37789}
}